Loading...
Loading...
Loading...

Beyond RAG:EverMemModel Achieves SOTA by Ingesting Entire Databases at Once

Beyond RAG:EverMemModel Achieves SOTA by Ingesting Entire Databases at Once

The EverMemModel has achieved SOTA performance both on retrieval task and QA task.

EverMind researchers

About 1 minutes to read

SOTA
Beyond RAG:EverMemModel Achieves SOTA by Ingesting Entire Databases at Once

The EverMemModel achieves a technological breakthrough by allowing users to input the entire retrieval database along with their query into the model, which then rapidly returns reference document IDs and answers.

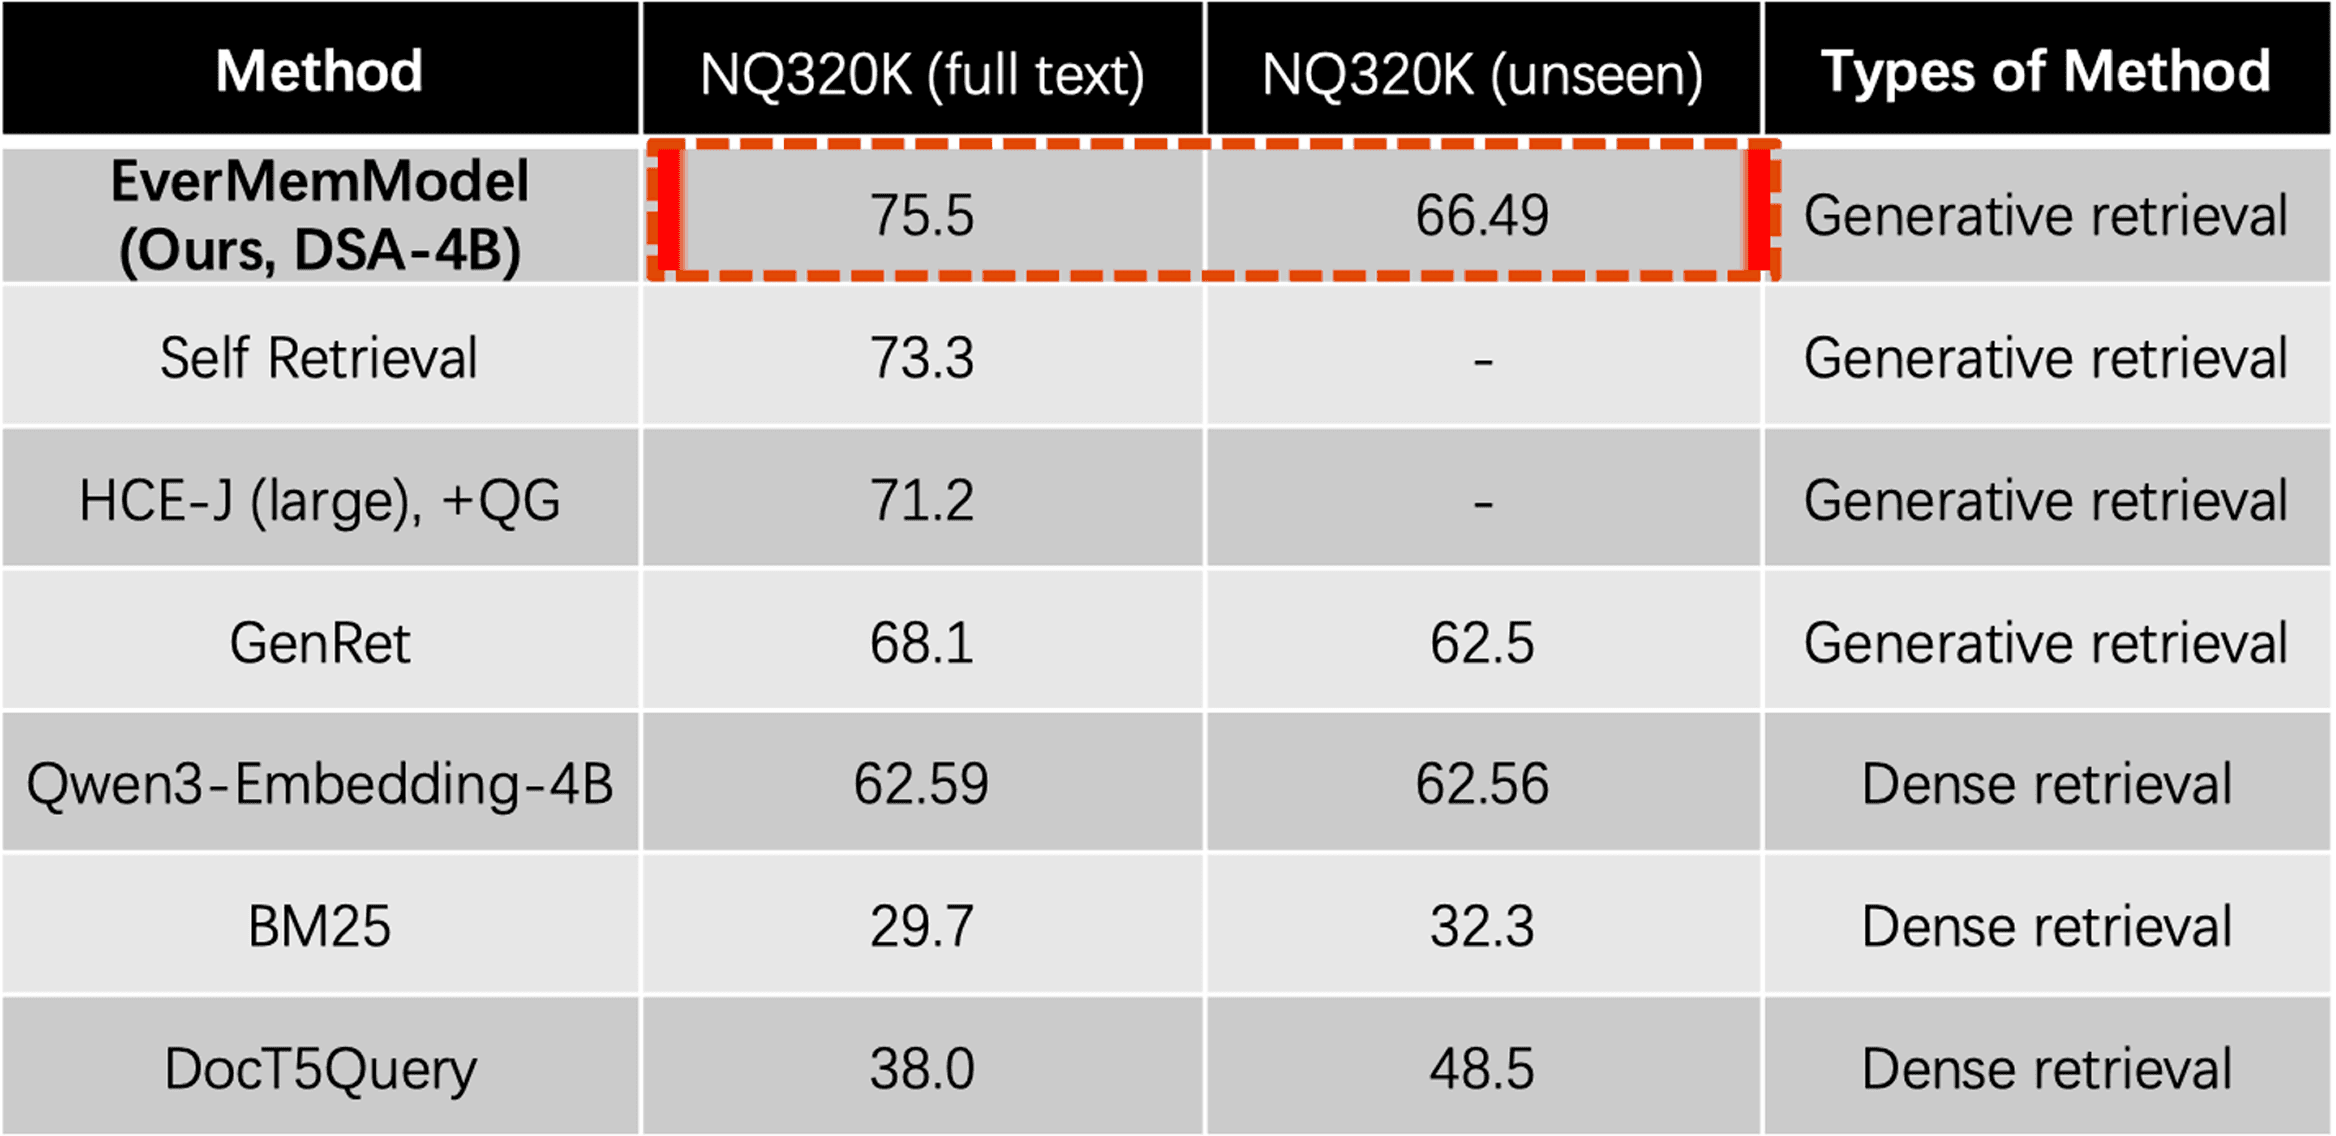
Retrieval Task: On NQ320K (full text), it achieves a Recall@1 of 75.5. For the unseen test set, the Recall@1 metric reaches 66.49, ultimately achieving SOTA on both NQ320K leaderboards.

table 1

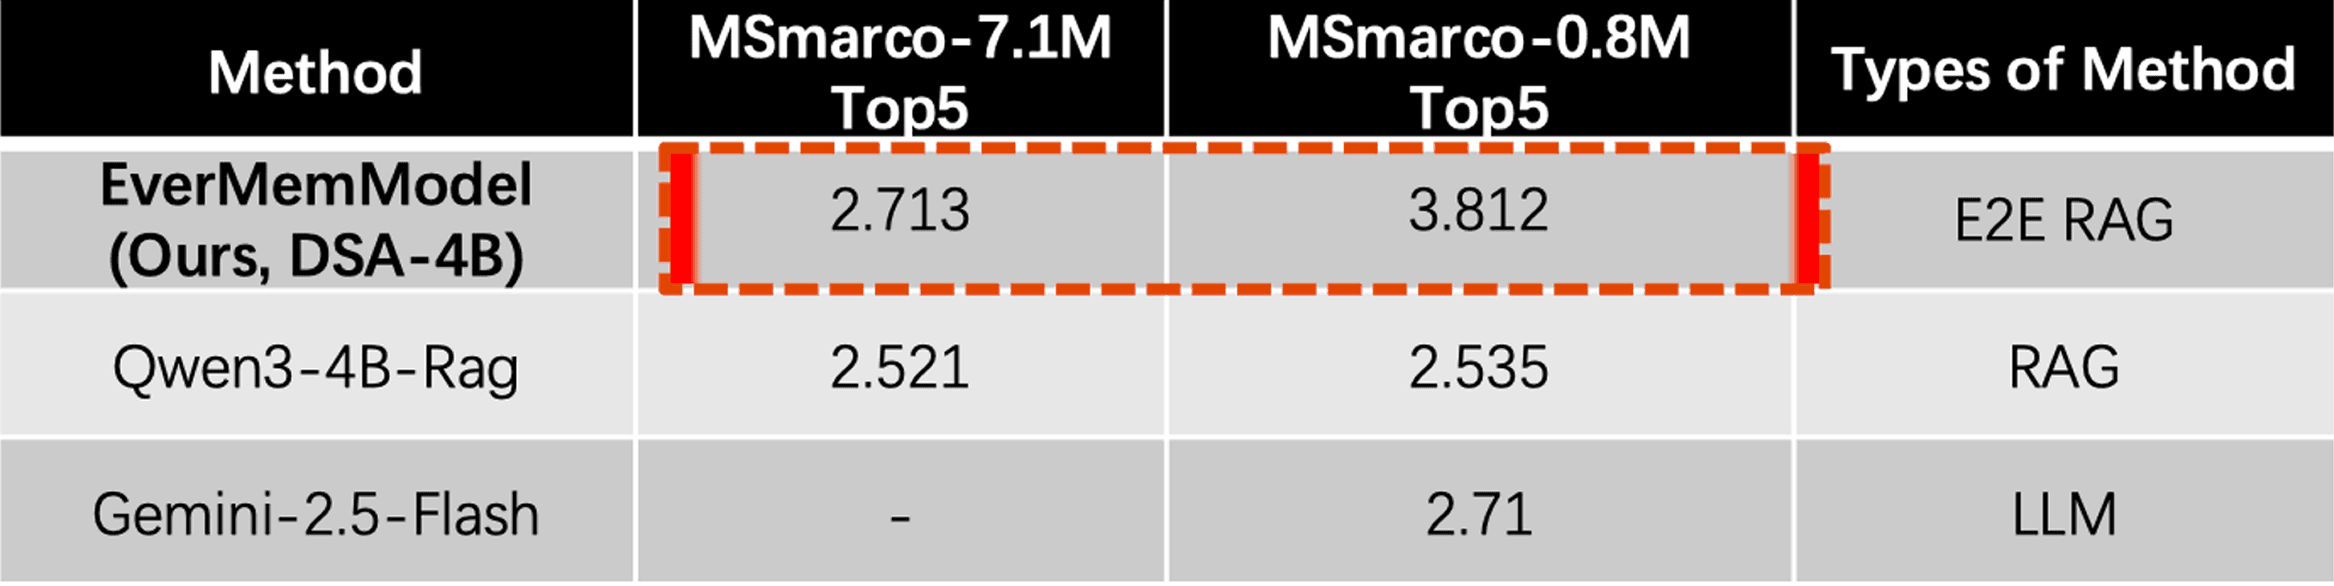
QA Task: The DSA method performs QA directly on contexts up to 7.1M in length without relying on Embedding retrieval. When compared to the RAG method based on Qwen3-Embedding-4B + Qwen3-4B-Instruct and the Gemini 2.5 Flash method, it outperforms both (the metric in the table is the LLM Judgment score for Gemini 2.5).

table 2

The EverMemModel achieves a technological breakthrough by allowing users to input the entire retrieval database along with their query into the model, which then rapidly returns reference document IDs and answers.

Retrieval Task: On NQ320K (full text), it achieves a Recall@1 of 75.5. For the unseen test set, the Recall@1 metric reaches 66.49, ultimately achieving SOTA on both NQ320K leaderboards.

table 1

QA Task: The DSA method performs QA directly on contexts up to 7.1M in length without relying on Embedding retrieval. When compared to the RAG method based on Qwen3-Embedding-4B + Qwen3-4B-Instruct and the Gemini 2.5 Flash method, it outperforms both (the metric in the table is the LLM Judgment score for Gemini 2.5).

table 2
Loading...
Loading...

You may also like these

Related

Multi-round retrieval: letting the model decide when to stop searching

Multi-round retrieval: letting the model decide when to stop searching

multi-round retrieval,agentic retrieval,fixed top-k,injection budget,core selection,EverOS,agent memory,LoCoMo,LongMemEval,EverMemBench,SubtleMemory,multi-hop retrieval,retrieval accuracy,prompt token cost

SkillCorpus paper title card

Do public SKILL.md files actually make agents better?

SkillCorpus,SKILL.md,agent skills,skill curation,skill retrieval,LLM agents,SkillsBench,GDPVal,agent harness

CRAFT paper title card

CRAFT: learning how to fuse video tokens, not just which to drop

CRAFT,video token compression,vision-language models,video VLM,KV cache,prefill cost,token merging,token pruning,temporal reasoning

HarnessBank paper title card

Self-evolving agents have a measurement problem

self-evolving agents,agent harness,HarnessBank,credit assignment,LLM agents,agent evaluation,harness optimization,significance testing

Beyond RAG:EverMemModel Achieves SOTA by Ingesting Entire Databases at Once

The EverMemModel has achieved SOTA performance both on retrieval task and QA task.

EverMind researchers

About 1 minutes to read

SOTA

EverMind

A straightforward solution to long-term coherence

Scan to join the community

Discord

Wechat

© 2026 EverMind Team.

EverMind

A straightforward solution to long-term coherence

Scan to join the community

Discord

Wechat

© 2026 EverMind Team.

EverMind

A straightforward solution to long-term coherence

Scan to join the community

Discord

Wechat

© 2026 EverMind Team.